How to Use AI to Standardise, Categorise and Match Customer Data
AI-assisted data cleaning works best when you give it a narrow task, a defined output and examples of what should stay unchanged. “Clean this database” leaves too much room for interpretation. “Suggest category mappings and flag uncertain records” is easier to inspect and repeat.
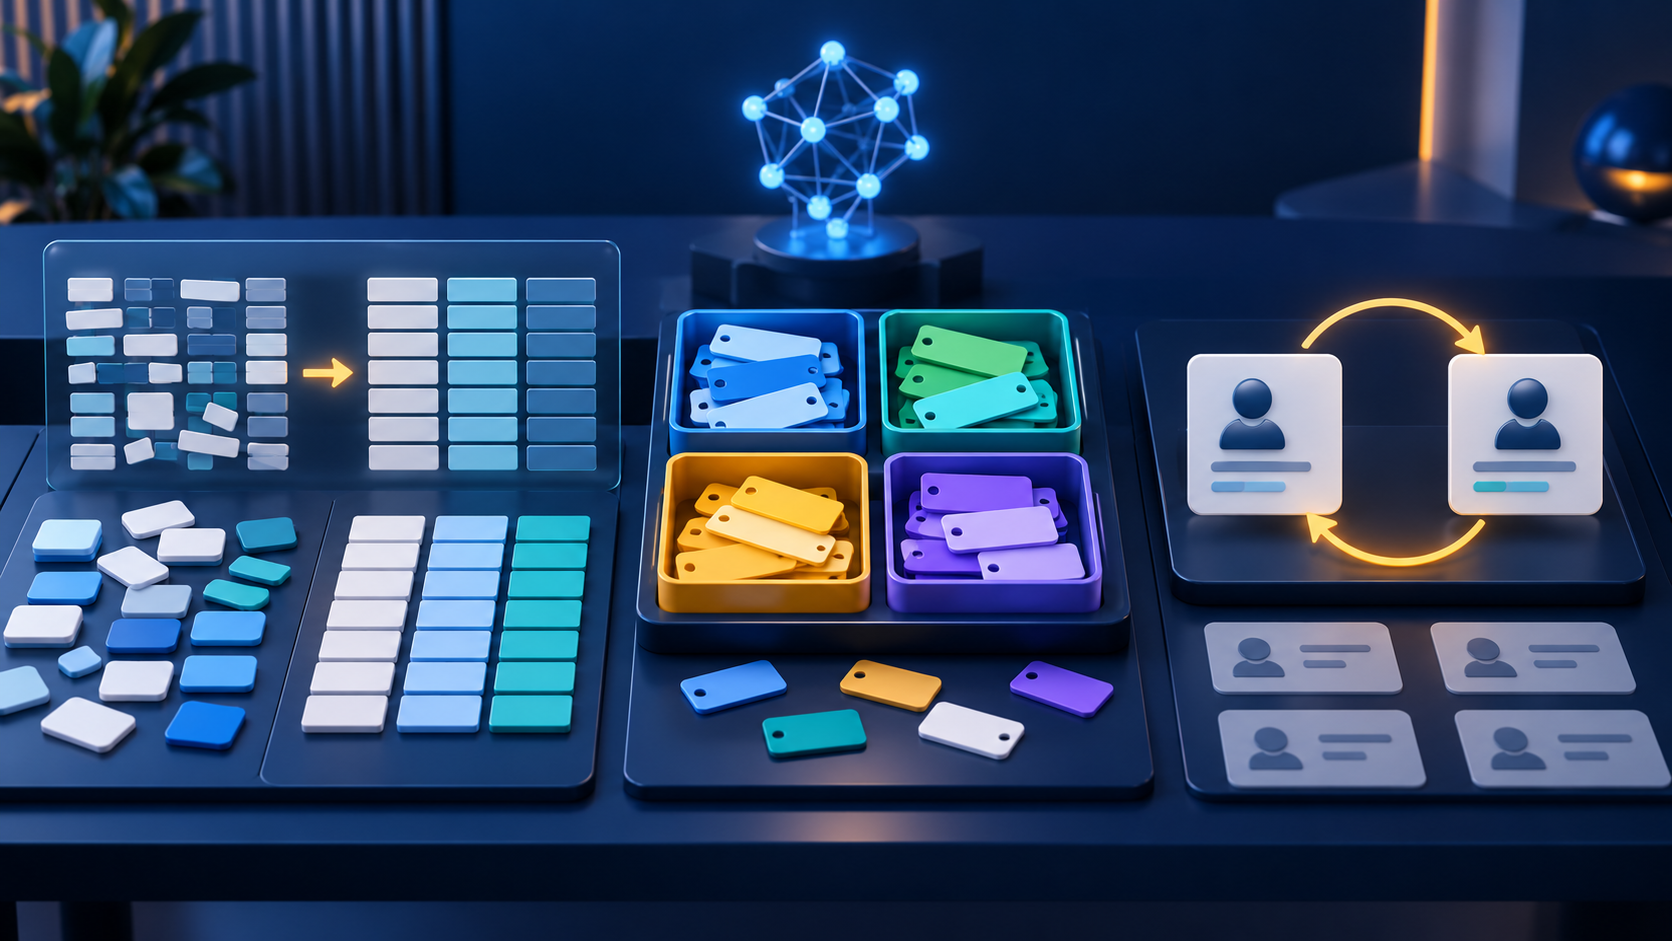
This practical guide covers three preparation jobs: standardising inconsistent formats, categorising enquiry text and finding possible duplicates. It explains how to turn suggestions into controlled changes before updating your CRM.
For the separate question of what a tool can establish about real contact details, read Can AI Clean Your Customer Data? What It Can and Can’t Verify.
Start with a small, controlled sample
Choose a representative selection of records rather than your whole database. Include ordinary entries, awkward cases and records that look similar but should remain separate. Keep the original values and stable record IDs.
Use synthetic examples to develop your instructions where possible. Before sharing real customer information with an AI service, confirm that your organisation has approved the purpose and the provider’s data-handling arrangements. Do not upload unnecessary personal fields simply because they appear in an export.
Write down the decision you want to support. A reporting tidy-up, a duplicate review and a marketing campaign are different jobs, even if they start with the same file.
Task 1: standardise formats without inventing facts
Formatting is about representation. It might involve removing stray spaces, mapping agreed abbreviations or expressing a known value consistently. It should not silently change the underlying fact.
| Illustrative input | Reasonable handling | What to avoid |
|---|---|---|
| A company field with extra spaces | Trim unwanted spacing and preserve the source | Changing the legal name based on a guess |
| A date written as 03/04/2026 | Ask for the source convention or flag ambiguity | Assuming day and month order without evidence |
| A mobile number missing a digit | Flag an incomplete value for review | Inventing a digit to pass a length check |
| Several approved labels for the same source | Map them using an agreed lookup table | Adding unrelated sources to make every row fit |
A useful instruction for this task
Review these synthetic records for inconsistent formatting. Return record ID, original value, proposed value, rule used and review status. Preserve unknown values. Do not infer missing digits, dates, identities or contact details. Flag ambiguous cases instead of correcting them.
Inspect the proposed rules before applying them to the full file. Once a transformation is clear and repeatable, a spreadsheet formula, lookup table or import rule may be a better way to run it consistently.
Be particularly careful with names. Similar spellings and unfamiliar punctuation are not evidence that a person’s name is wrong.
Task 2: categorise enquiry text against an agreed scheme
Free-text enquiries often contain useful information that is difficult to report on. AI can suggest categories, but the categories should follow your business process rather than appear differently in each run.
For example, you might define “new sales enquiry”, “billing”, “technical support” and “needs review”. Give each category a description and include examples that sit on the boundary between two choices.
Make uncertainty an allowed output
A message saying “I cannot get my account to work and I have a charge to query” may span support and billing. Decide whether multiple labels are allowed or whether the record should be reviewed.
If you force every message into exactly one category, you may get a tidy report that hides the mixed nature of the enquiries. A small review group is often more useful than confident but inappropriate labels.
A useful instruction for this task
Classify each synthetic enquiry using only the supplied categories and their definitions. Return record ID, suggested category, a short reason and any ambiguity. If no category fits, use “needs review”. Do not infer personal characteristics or add information that is absent from the enquiry.
Compare the suggestions with a sample labelled by someone who understands the workflow. Look at which categories are confused, not just the overall proportion that looks reasonable. Misrouting an urgent support request may matter more than a minor reporting mismatch.
Task 3: find possible duplicates without merging automatically
Duplicate detection is about identifying records that may describe the same person or organisation. It is not simply a search for repeated names.
Two contacts called Alex Taylor might be different people. Two records for the same company might represent different branches. A shared accounts inbox could legitimately appear against several customer accounts.
Return candidate pairs and the evidence
Ask the system to suggest pairs for review, with the fields that support the match and anything that conflicts. Keep source IDs in the output so each decision can be traced back.
Identify possible duplicate pairs in these synthetic records. Return both record IDs, matching evidence, conflicting evidence and a proposed review action. Do not merge records. Treat shared names, addresses and inboxes as clues rather than proof of identity.
A similarity score can help prioritise the queue, but it does not establish identity. Set your merge rules using reliable identifiers and a review process suited to the consequences of a mistake.
When a merge is justified, decide which fields survive and preserve important history and objections. An older opt-out must not disappear simply because the newer record has a cleaner layout.
Separate cleaning suggestions from contact verification
After preparation, check the facts needed for the next workflow. Tidying an email string does not prove that the intended mailbox exists. Consistent phone formatting does not establish current mobile-network status.
- Use email verification to assess technical email signals.
- Use mobile validation for relevant network information.
- Use PAF validation to assess UK postal addresses against reference data.
- Apply current preference and suppression checks where relevant to the intended contact.
Each result has limits. Technical validity does not establish identity or permission to send marketing. Keep proposed changes, observed validation results and final business decisions in separate fields.
Check the output before importing changes
A practical review should answer the following questions:
- Did every output row retain its source ID?
- Were unknown values preserved rather than filled with guesses?
- Did the instructions produce the agreed categories and formats?
- Were separate people or branches incorrectly suggested as matches?
- Are uncertain cases visible?
- Will the import preserve preferences, newer customer updates and history?
Test the import on a controlled subset. Reconcile record counts and compare important fields before and after the change. Keep an appropriate recovery route for the affected records.
Measure whether the process actually helps
Track reviewed and accepted suggestions, false matches, corrections reversed and manual review time. A system that fills every blank or proposes many merges is not necessarily improving data quality.
Retest when the model, instructions, source data or business categories change. Keep the version of the rules with the job record so later teams can understand how the changes were produced.
Frequently asked questions
Do we need AI for every cleaning task?
No. Fixed transformations often suit ordinary rules. Use AI where handling variation or interpreting text adds useful value.
Should a model’s confidence score decide whether to merge?
No score should replace a justified matching policy. Evaluate the evidence and the effect of an incorrect merge.
Can we run the same instructions on every new supplier file?
Only after checking the layout, definitions and source conventions. A familiar column name does not guarantee that the values mean the same thing.
Turn suggestions into a repeatable workflow
Start narrow, preserve the originals and test on difficult examples. Use AI to suggest useful transformations, then apply the evidence and review needed for the decision.
For a broader introduction, read our data scrubbing guide. Explore DataSoap’s validation services or discuss your customer-data workflow with the team.
Put clean data to work on your own list.
£100 of credits for £4.99. New customers, once.